Production notes
- Image denoising to token masking translation
- Confidence-based parallel decoding walkthrough
- GPU utilization comparison: sequential bursts vs saturated parallel passes
- Sequence-length scaling animation: 512 passes vs 64 denoising steps
- Side-by-side tokens-per-second race
Explainer
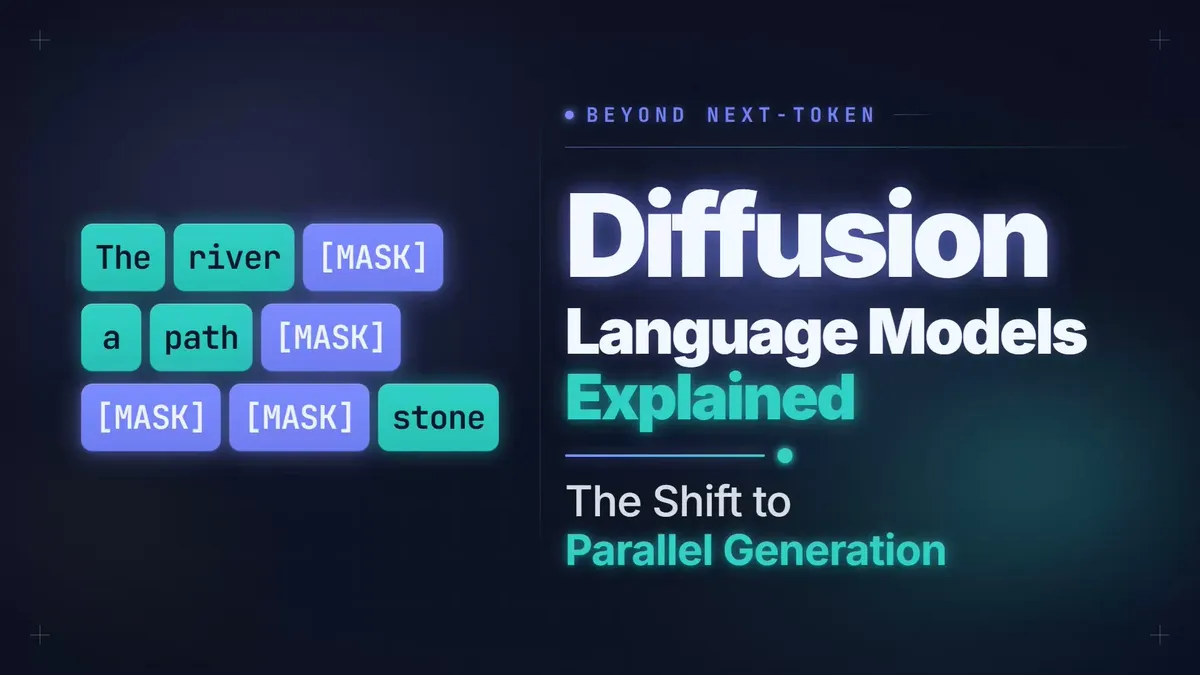
Diffusion Language Models Explained: The Shift to Parallel Generation
Why every LLM writes one token at a time, and how diffusion models denoise whole responses in parallel to reach over 1,000 tokens per second.
5:42 Software Engineers Intermediate