Examples

See what we produce.

Every video below was produced end-to-end with Clyep: script, visuals, narration, and all.

Diffusion Language Models Explained: The Shift to Parallel Generation Featured

Production notes

  • Image denoising to token masking translation
  • Confidence-based parallel decoding walkthrough
  • GPU utilization comparison: sequential bursts vs saturated parallel passes
  • Sequence-length scaling animation: 512 passes vs 64 denoising steps
  • Side-by-side tokens-per-second race
Explainer

Diffusion Language Models Explained: The Shift to Parallel Generation

Why every LLM writes one token at a time, and how diffusion models denoise whole responses in parallel to reach over 1,000 tokens per second.

5:42 Software Engineers Intermediate
Forward Deployed Engineering: What It Is, What It Isn't, and When It Matters

Production notes

  • Three-role comparison diagram: software, implementation, and product
  • Adoption gap visualization with the capability-to-value flip
  • Margin profile comparison: product vs consulting economics
  • Productization loop animation from field back to core product
  • Four-condition checklist build-up
Industry Insights Explainer

Forward Deployed Engineering: What It Is, What It Isn't, and When It Matters

What forward deployed engineers actually do, why the role is exploding in the AI era, and the four conditions a company must meet before standing one up.

7:38 Technical Leadership All levels
KV Cache and RadixAttention: How LLM Servers Avoid Redundant Computation

Production notes

  • Token-by-token recomputation triangle animation
  • Quadratic-to-linear staircase collapse visualization
  • Cross-request redundancy at 10, 100, and 1,000 concurrent requests
  • RadixAttention prefix tree build-up with branch-and-reuse walkthroughs
  • Same GPU, same model speed comparison
Explainer

KV Cache and RadixAttention: How LLM Servers Avoid Redundant Computation

How the KV cache turns quadratic recomputation into linear work, and how RadixAttention shares cached prefixes across thousands of concurrent requests.

4:24 ML Engineers Intermediate
Continuous Batching: Dynamic Request Scheduling for LLM Inference

Production notes

  • Real-time GPU batch timeline visualization
  • Hybrid prefill-decode step animations
  • Dynamic batch membership tracking
  • Token generation counter with step metrics
Explainer

Continuous Batching: Dynamic Request Scheduling for LLM Inference

How continuous batching fixes static batching's GPU waste by letting requests join and leave dynamically.

7:54 ML Engineers Intermediate
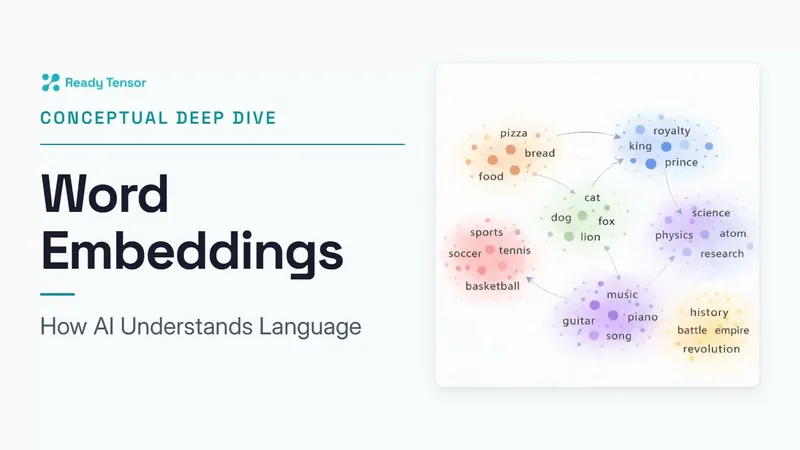
Word Embeddings: How AI Understands Language

Production notes

  • Real embedding experiments visualized with t-SNE maps
  • Animated vector arithmetic (king - man + woman = queen)
  • Side-by-side model comparison
  • Cosine similarity angle visualizations
  • Semantic search vs keyword search demo
Explainer

Word Embeddings: How AI Understands Language

How computers learned to understand language, from word vectors to semantic search, explained visually.

10:55 All audiences Beginner
Harness Engineering: The Bottleneck Moved

Production notes

  • Animated quote callouts with speaker attribution
  • Architecture diagrams showing agent-harness relationship
  • Case study data visualizations
  • Series-aware ending with Part 2 teaser
Industry Insights Explainer

Harness Engineering: The Bottleneck Moved

Why top engineers at OpenAI and Stripe have stopped writing code, and what they're building instead.

4:13 Software Engineers All levels
Harness Engineering: Control, Context, and Checks

Production notes

  • Agent workflow failure visualization
  • Sandboxed environment lifecycle animation
  • Progressive disclosure vs ambient context comparison
  • Verification theatre vs independent checks demo
Industry Insights Explainer

Harness Engineering: Control, Context, and Checks

How to make AI coding agents reliable in production with three pillars: sandboxed control, curated context, and independent verification.

5:56 Software Engineers All levels
Product Demo: Workflow Automation with n8n

Production notes

  • Visual workflow builder walkthrough
  • Three-node automation built from scratch
  • Template library showcase
  • Narration-synced node connections
Product Demo

Product Demo: Workflow Automation with n8n

Build a Gmail-to-Slack automation with AI summarization using n8n's visual workflow builder — zero code, three nodes, deployed in minutes.

4:41 All audiences Beginner
Durable Execution: Reliability Without the Sprawl

Production notes

  • Step-by-step workflow failure visualization
  • Before/after reliability machinery comparison
  • Checkpoint and crash recovery animation
  • Runtime vs application code architecture diagram
Explainer

Durable Execution: Reliability Without the Sprawl

What happens after your API returns 202. How durable execution shifts retry logic, state tracking, and crash recovery out of your code and into a runtime.

4:56 Software Engineers Intermediate
LangSmith Tutorial: Observability & Tracing for AI Agents

Production notes

  • Environment variable setup walkthrough
  • Live terminal output showing trace capture
  • LangSmith dashboard monitoring demo
  • Narration-synced code highlighting
Product Demo Developer Tutorial

LangSmith Tutorial: Observability & Tracing for AI Agents

Set up LangSmith from scratch and trace every step your AI agent takes, from environment config to production monitoring.

2:50 AI/ML Developers Beginner
Mercury 2: The Fastest Reasoning Language Model

Production notes

  • Autoregressive vs diffusion architecture comparison
  • Parallel token refinement visualization
  • Speed benchmark animations
  • Zed editor integration demo
Explainer Product Demo

Mercury 2: The Fastest Reasoning Language Model

How Mercury 2 by Inception Labs breaks the autoregressive bottleneck with diffusion-based parallel token generation to achieve 1,009 tokens per second.

3:54 ML Engineers Intermediate
Prompt Caching Explained: Why Prefixes Matter

Production notes

  • Two identical prompts with a 10x cost gap reveal
  • Token-by-token KV vector computation animation
  • Stable head vs variable tail prompt breakdown
  • Prefix tree build-up with cache hit and miss walkthroughs
  • Cache eviction and its cost and latency impact
Explainer

Prompt Caching Explained: Why Prefixes Matter

Why two identical prompts can cost 10x differently, and how KV caching and prefix trees decide which calls you pay full price for.

6:01 Software Engineers Intermediate
Event-Driven Architecture: Promise, Pitfalls, and Patterns

Production notes

  • Animated event fan-out and failure scenarios
  • Producer-broker-consumer flow diagrams
  • Idempotency and traceability pattern visualizations
  • Side-by-side expected vs actual behavior comparisons
Explainer

Event-Driven Architecture: Promise, Pitfalls, and Patterns

What event-driven architecture actually looks like in production: delivery guarantees, ordering problems, and the patterns that make it work.

6:25 Software Engineers Intermediate
How Encryption Works: From Shared Secrets to Public Keys

Production notes

  • Raw ciphertext visualization from real network traffic
  • Animated symmetric key lock-unlock flow
  • Padlock analogy for public-private key pairs
  • Multi-party messaging diagram with Eve interception
Explainer Training

How Encryption Works: From Shared Secrets to Public Keys

Symmetric and asymmetric encryption explained visually, from shared secrets to public-private key pairs.

4:44 All audiences Beginner
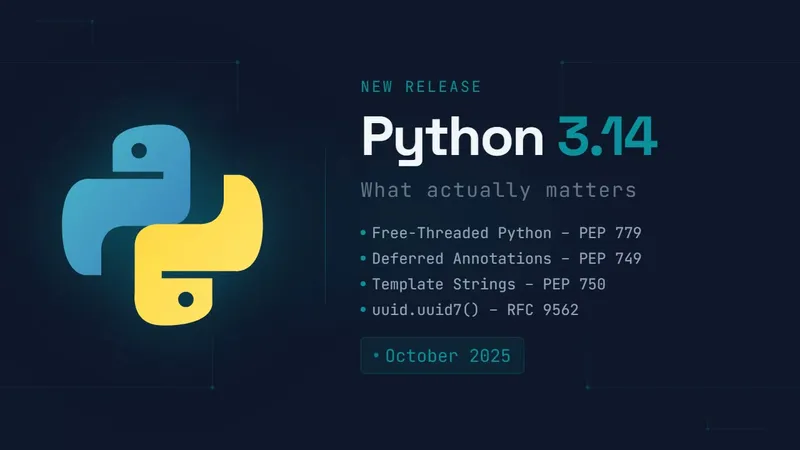
Python 3.14: What Actually Matters

Production notes

  • Animated code examples for t-strings and type annotations
  • GIL threading visualization
  • Before/after comparisons for each feature
  • Clean recap summary
Release Update Developer Tutorial

Python 3.14: What Actually Matters

T-strings, deferred type annotations, free-threaded builds, and UUID7. The key features in Python 3.14.

4:08 Python Developers All levels
Speculative Decoding: Faster LLM Inference

Production notes

  • Animated token-by-token generation timeline
  • Draft-verify cycle visualization
  • Side-by-side autoregressive vs speculative timing comparison
  • Three-parameter speedup breakdown
Explainer

Speculative Decoding: Faster LLM Inference

How speculative decoding uses a small draft model to speed up large language model inference, explained visually.

9:15 ML Engineers Intermediate
Building an AI Team: A Practical Playbook

Production notes

  • Animated org chart and team structure diagrams
  • Data visualizations with BCG and Microsoft statistics
  • 120-day timeline with milestone markers
  • Budget breakdown with cost annotations
Industry Insights Training

Building an AI Team: A Practical Playbook

A practical guide to building a five-person AI team for mid-sized companies, from first hire to first win in 120 days.

13:24 Technical Leadership All levels
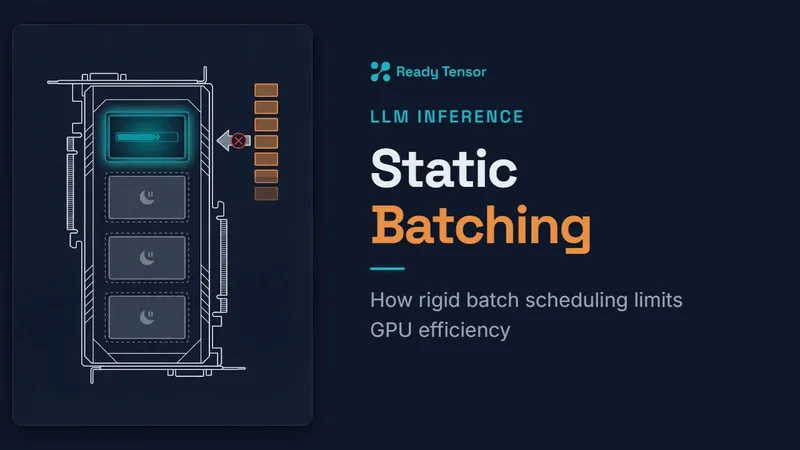
Static Batching: How Batch Scheduling Limits GPU Efficiency

Production notes

  • Real-time GPU batch timeline visualization
  • Animated slot filling and idle tracking
  • Queue starvation counter
  • Phase-by-phase walkthrough with metric overlays
Explainer

Static Batching: How Batch Scheduling Limits GPU Efficiency

A visual walkthrough of static batching for LLM inference, and why it wastes GPU cycles at scale.

5:19 ML Engineers Intermediate

All videos produced end-to-end with Clyep.

Ready to ship?

Need something specific to your product?

Tell us what you're looking for. We'll be in touch ASAP to discuss next steps.